--- title: Welcome to SGLang description: High-performance serving framework for large language and multimodal models. keywords: - sglang - llm serving - multimodal - inference runtime mode: wide --- import { popularModels } from "/src/snippets/configs/popular-models.jsx"; import { PopularModels } from "/src/snippets/_popular_models.jsx"; {/* One hero per model, rotating. The Cookbook landing page renders the same list as a compact strip. Edit the list, not this page. */} Star Fork

Designed for low-latency, high-throughput inference with RadixAttention, prefix caching, and multi-GPU parallelism. Broad support for Llama, Qwen, DeepSeek, and more. Compatible with Hugging Face and OpenAI APIs. Native support across Hardware Platforms including NVIDIA, AMD, Intel Xeon, Google TPU, Ascend NPU, and Moore Threads MUSA accelerators. Open-source with widespread adoption, powering 400k+ GPUs and integrated with major RL frameworks. SGLang powers large-scale production deployments, generating trillions of tokens each day across more than 400,000 GPUs worldwide. It is hosted under the non-profit open-source organization [LMSYS](https://lmsys.org/about/). --- ## Get Started SGLang is an inference framework meant for production level serving. It is designed to deliver low-latency and high-throughput inference across a wide range of setups, from a single GPU to large distributed clusters. Install SGLang with pip, from source, or via Docker on your preferred hardware platform. Launch your first model server and send requests in minutes with OpenAI-compatible APIs. ## News and latest blogs {/* BEGIN_LMSYS_SGLANG_BLOG_CARDS */}
SGLang and Miles Add Day-0 Support for DeepSeek-V4.1

{"SGLang and Miles Add Day-0 Support for DeepSeek-V4.1"}

{"September 10, 2026"}
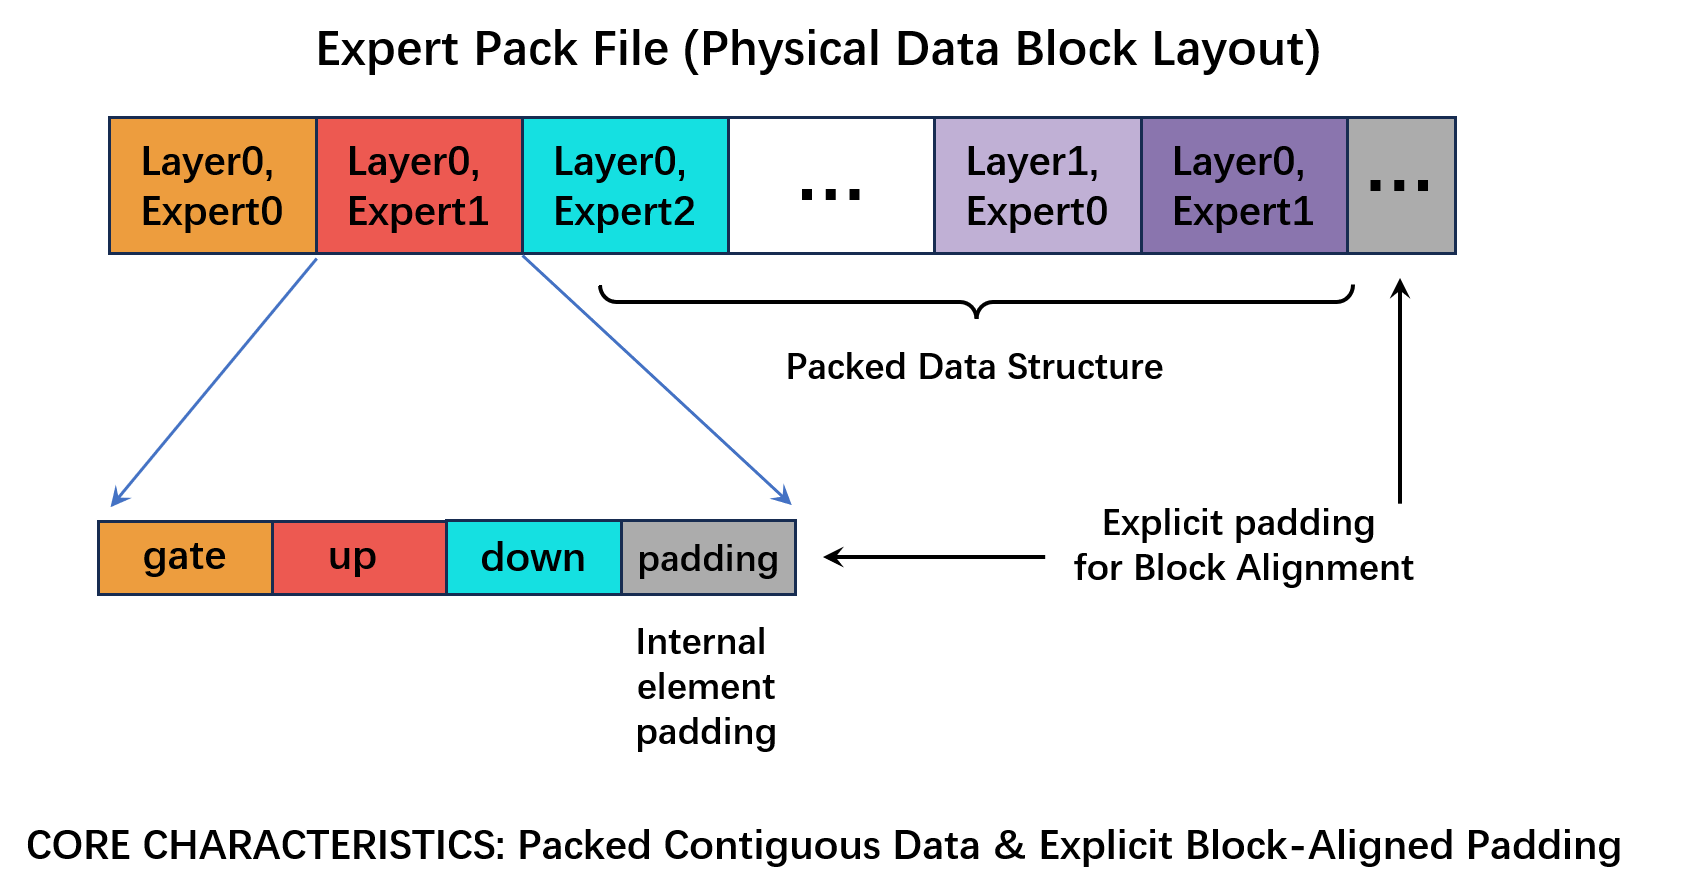
Running DeepSeek-V4-Flash and Kimi-K3 on Consumer Hardware with SSD Expert Pack

{"Running DeepSeek-V4-Flash and Kimi-K3 on Consumer Hardware with SSD Expert Pack"}

{"August 29, 2026"}
Infer-forge: Harness, Loop, and Graph Engineering Around SGLang

{"Infer-forge: Harness, Loop, and Graph Engineering Around SGLang"}

{"August 28, 2026"}
MiniMax-H3 on 8\u00d7H200: 1.95\u00d7 Lossless, Up to 6.24\u00d7 at 0.76\u20130.91 SSIM

{"MiniMax-H3 on 8\u00d7H200: 1.95\u00d7 Lossless, Up to 6.24\u00d7 at 0.76\u20130.91 SSIM"}

{"August 27, 2026"}
Qwen3.8-Flash-Next: Day-0 Support in SGLang

{"Qwen3.8-Flash-Next: Day-0 Support in SGLang"}

{"August 26, 2026"}
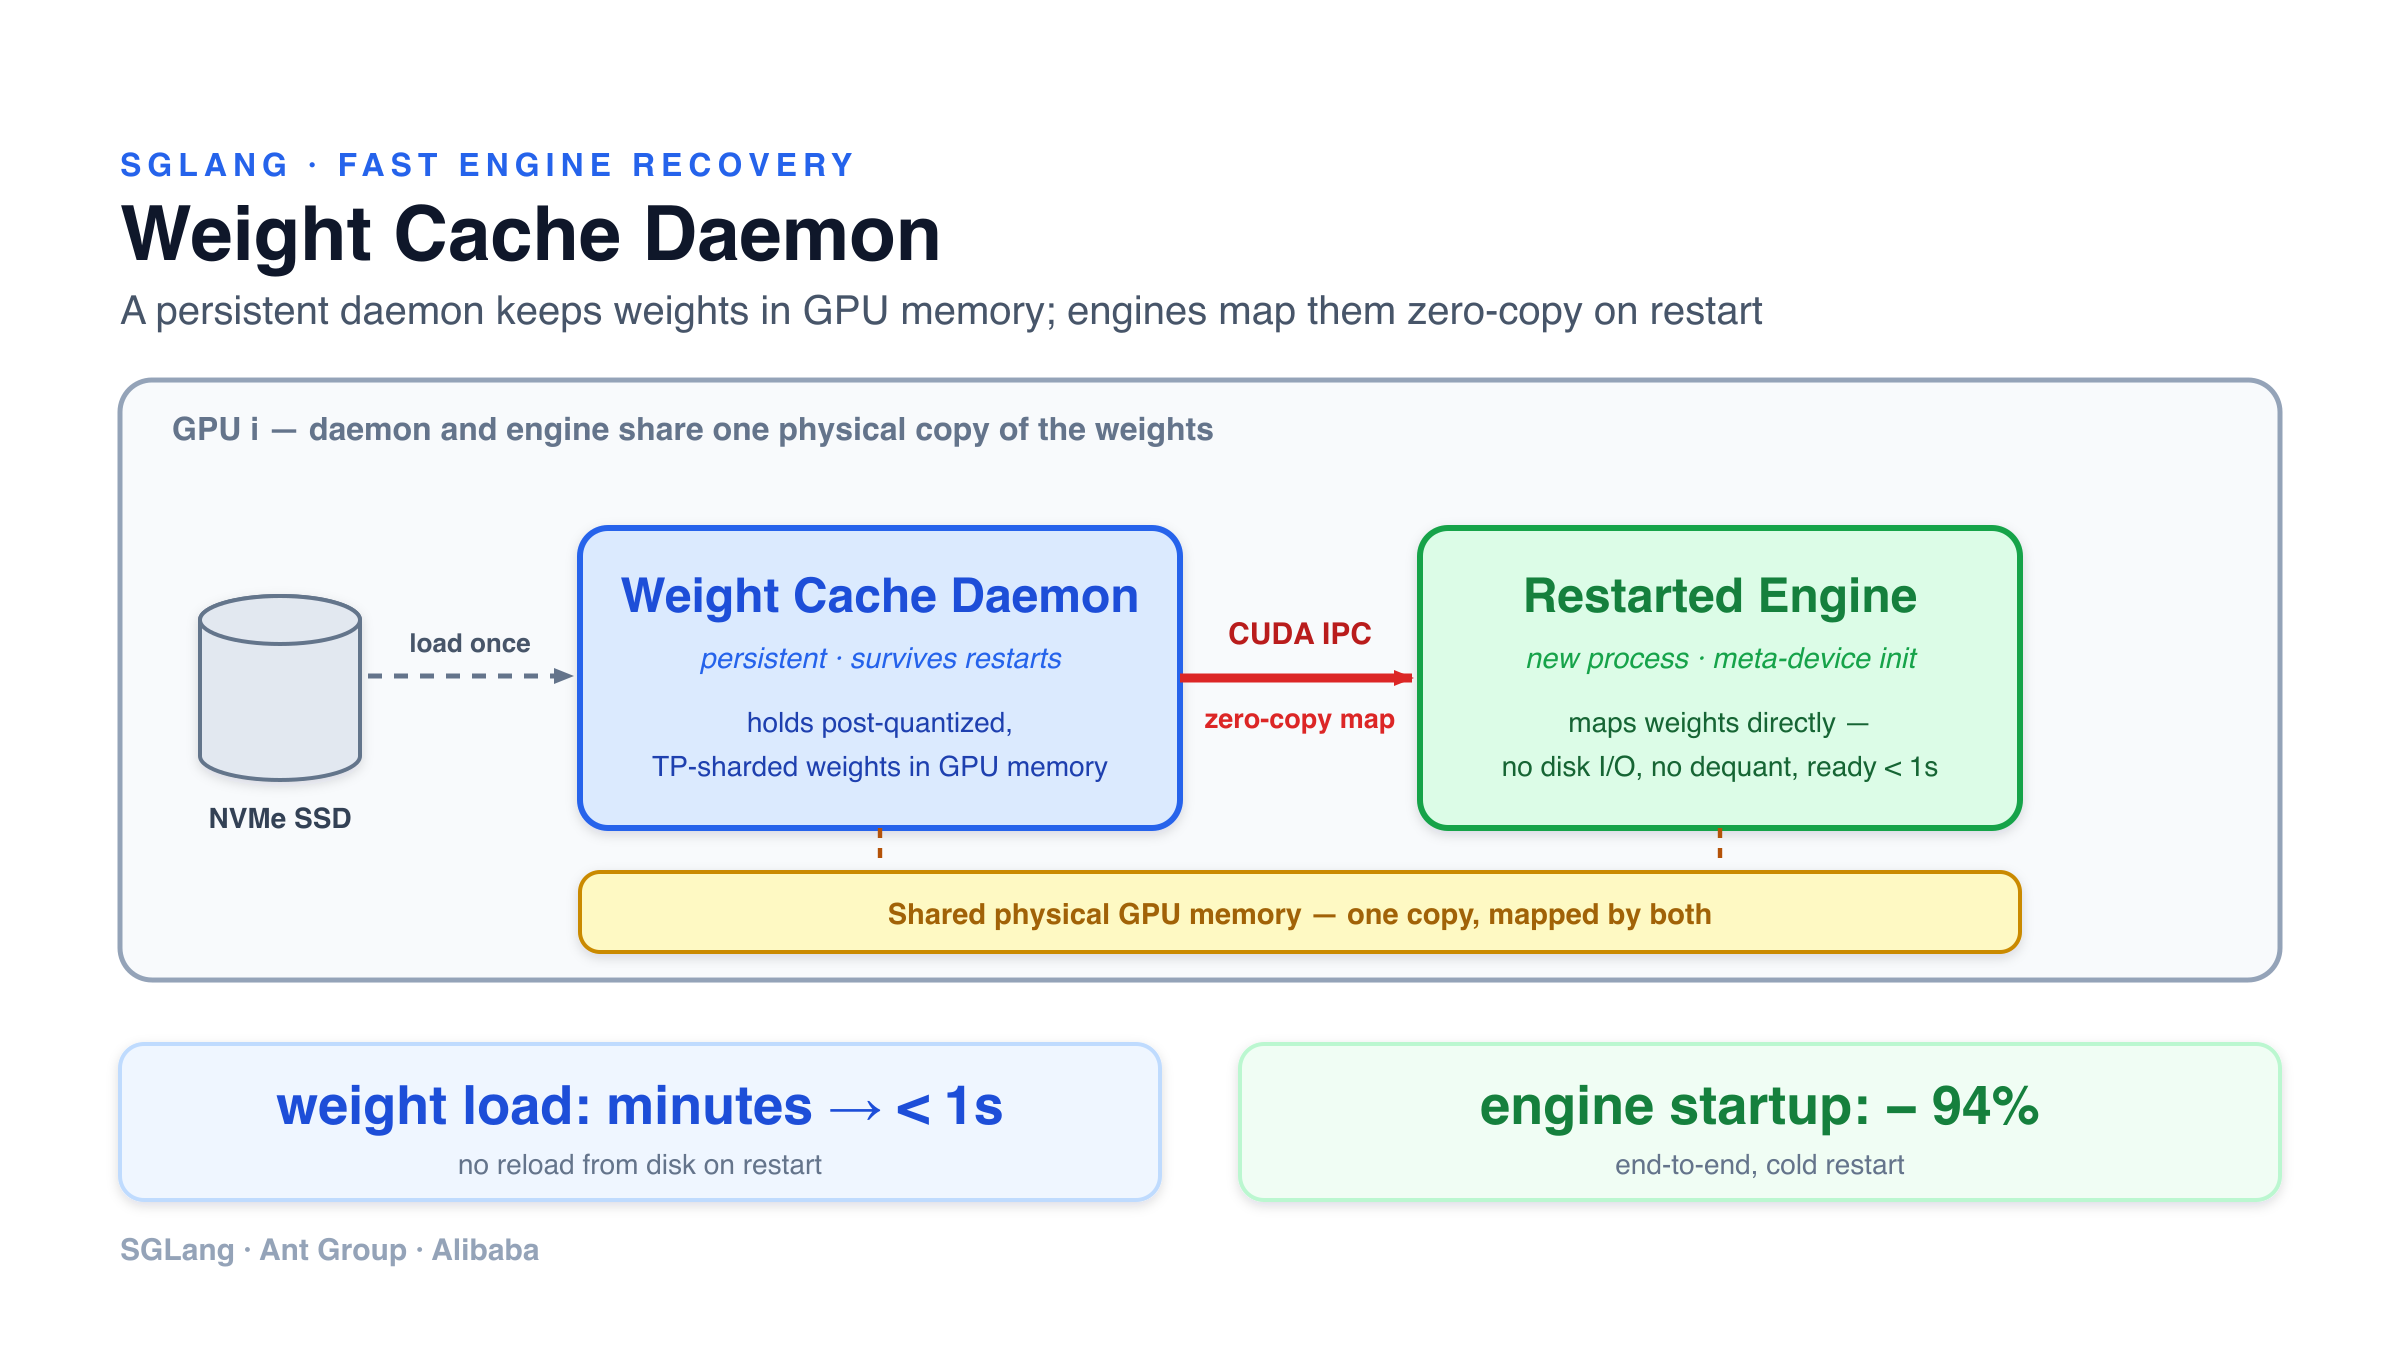
Fast Engine Recovery: Sub-Second Engine Restart for SGLang via Weight Cache Daemon

{"Fast Engine Recovery: Sub-Second Engine Restart for SGLang via Weight Cache Daemon"}

{"August 21, 2026"}

{/* END_LMSYS_SGLANG_BLOG_CARDS */} --- ## Learn more and join the community

Stay connected

{" "} Development roadmap to follow current priorities and upcoming work.
{" "} Weekly public development meeting to hear updates and join open discussions.
{" "} Slack for questions, feedback, and community support.
X Twitter and {" "} LinkedIn for project updates.
{" "} LMSYS blog for release notes, benchmarks, and technical deep dives.
{" "} Learning materials for blogs, slides, and videos.